Custom Enterprise AI Product Development & Intelligent Software Engineering
Transform proprietary business data and complex workflows into production-grade AI applications with enterprise-grade latency, deterministic guardrails, and measurable ROI.
Engineered for Commercial Impact.
Building commercial AI products requires far more than wrapping third-party API endpoints in a chat UI. Enterprise AI product development demands rigorous architecture: deterministic data pipelines, intelligent context caching, retrieval-augmented generation (RAG) with hybrid vector-graph indexing, and strict security boundaries. Accelerance designs and builds custom AI software products and SaaS applications that run reliably in high-concurrency environments. From custom predictive modeling to domain-adapted foundation models, we build IP-owned software assets that solve mission-critical operational challenges while minimizing inference token costs.
We believe your digital investments should produce compounding returns. By blending user-centric design with technical rigor, we eliminate friction and build durable digital advantages.
What Sets Our Approach Apart:
- Business-First Focus: We prioritize metrics that move the revenue needle over vanity numbers.
- Senior Execution: Experienced practitioners lead strategy, design, and deployment directly.
- Transparent Delivery: Real-time sprints, clear milestones, and zero proprietary lock-in.
Sub-800ms End-to-End Latency
Optimized model routing, semantic caching, and edge-deployed inference deliver instant user experiences.
Zero Proprietary Data Leakage
Isolated VPC architectures and localized model execution ensure enterprise IP is never used for foundation model training.
Predictable Token Economics
Dynamic model distillation and prompt token optimization reduce recurring inference costs by up to 65%.
Production-Grade Reliability (99.9% Uptime)
Circuit breakers, automated failovers across model providers, and deterministic schema outputs eliminate runtime failures.
Everything Needed to Scale
Modular, full-lifecycle solutions tailored to your operational model and growth milestones.
Generative AI SaaS Architecture
Greenfield engineering of scalable multi-tenant AI applications built on Next.js, FastAPI, Node.js, and cloud-native serverless backends.
Domain-Specific Model Fine-Tuning
Supervised fine-tuning (SFT) and Direct Preference Optimization (DPO) of open-weights models (Llama 3, Mistral) on proprietary enterprise corpora.
Enterprise RAG Systems
Multimodal retrieval architectures utilizing pgvector, Pinecone, or Qdrant with hybrid keyword/vector search, re-ranking, and citation transparency.
Hallucination Guardrail Engineering
Implementation of NeMo Guardrails, Llama Guard, and deterministic JSON-schema validation to ensure safe, legally compliant outputs.
Intelligent Data Pipelines
Automated data extraction, de-identification, chunking, and continuous embedding pipelines capable of ingesting terabytes of unstructured documents.
Continuous Eval & Observability
Real-time monitoring of response drift, semantic similarity, latency percentiles, and cost attribution through Langfuse, Arize Phoenix, and Datadog.
See How We Deliver Value

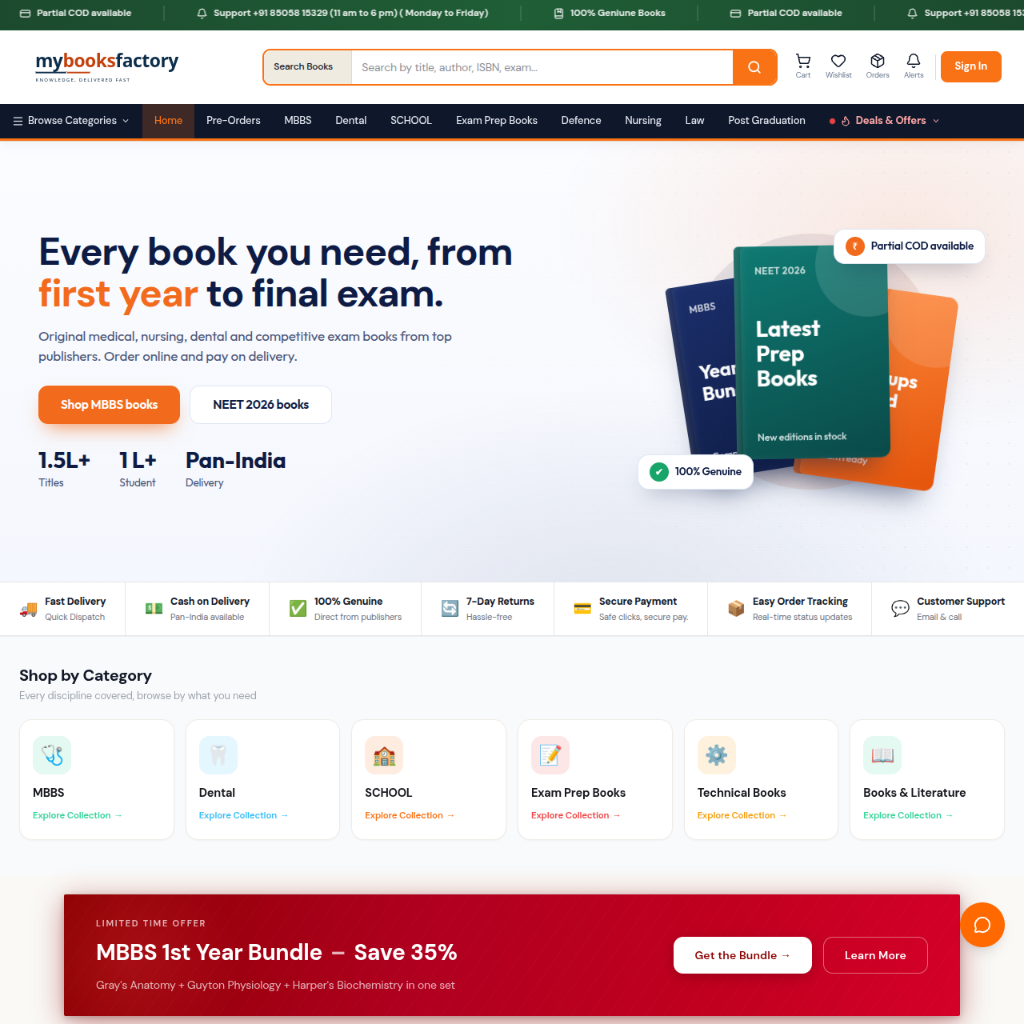
MyBooksFactory — Mybooksfactory.com
MyBooksFactory specializes in medical (MBBS, BDS), engineering, and competitive examination textbooks. We re-engineered their eCommerce platform to handle 40,000+ SKUs with sub-second catalog search and streamlined checkout, boosting sales during peak academic enrollment seasons.
Read Case Study →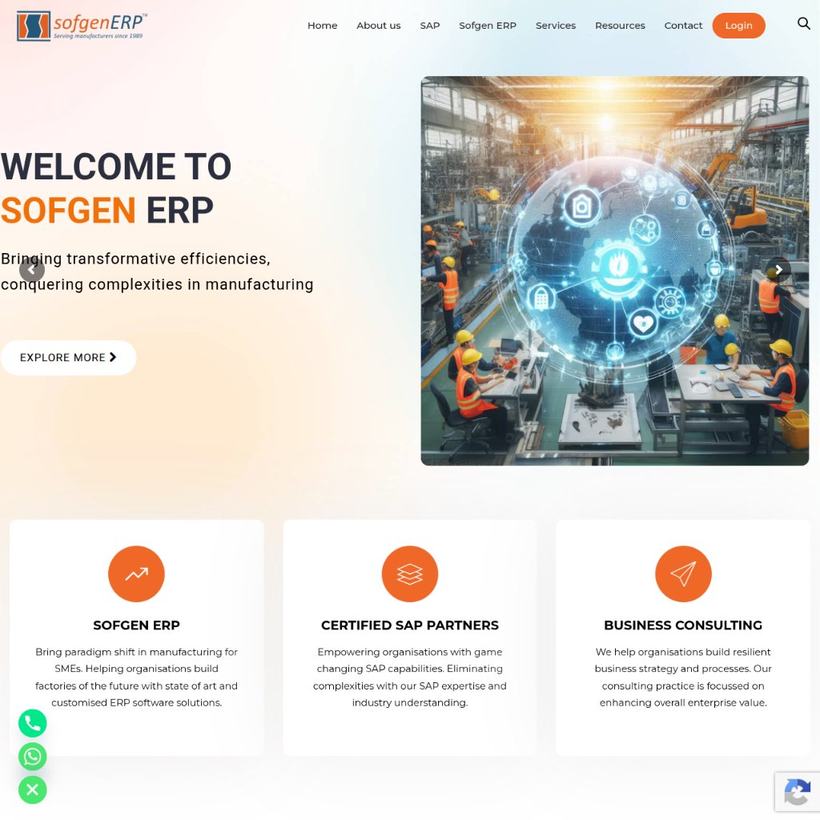
Sofgen ERP — Sofgen.org
Serving high-volume manufacturers since 1989, Sofgen required a cutting-edge digital enterprise flagship to showcase their custom ERP capabilities, certified SAP partnership, and industry 4.0 automation systems. We delivered a performance-optimized Next.js web application with sub-second page loads, structured B2B lead generation funnels, and enterprise solution discovery.
Read Case Study →Frequently Asked Questions
What is the difference between a prototype AI wrapper and an enterprise AI product?
A prototype wrapper simply passes raw user text to an external API like OpenAI without guardrails, semantic caching, or data validation. An enterprise AI product features custom data ingestion pipelines, hybrid retrieval-augmented generation (RAG), deterministic schema validation, token cost optimizations, role-based access control (RBAC), and strict privacy compliance.*
How does Accelerance protect our proprietary company data during AI development?
We deploy zero-data-retention API architectures and private VPC-hosted models on AWS, GCP, or Azure. Your data is encrypted at rest and in transit (AES-256 / TLS 1.3), and we guarantee in writing that proprietary data is never used to train public foundation models.*
How long does it take to deploy a custom AI SaaS MVP?
A production-ready AI Minimum Viable Product (MVP) typically takes 8 to 12 weeks from initial scoping to live user onboarding, including data pipeline configuration, UI/UX engineering, and safety testing.*
How do you prevent hallucinations in business-critical AI applications?
We utilize multi-stage mitigation: strictly grounded RAG with contextual chunking, automated cross-encoder re-ranking, bidirectional hallucination detection layers, and programmatic fallback rules that reject queries lacking source evidence.*
Let’s discuss your project goals.
Connect with our solution architects for a complimentary review of your current systems, roadmap, and growth targets.