Enterprise AI Integrations & High-Performance API Development
Seamlessly embed cutting-edge AI capabilities into your existing software infrastructure with secure, low-latency API architectures and microservices.
Engineered for Commercial Impact.
Integrating artificial intelligence into established enterprise ecosystems requires sophisticated backend engineering. Legacy databases, custom ERPs, and legacy applications cannot easily interface with non-deterministic LLMs without robust middleware. Accelerance builds resilient, high-throughput AI API layers and microservices that act as the intelligent connective tissue between your core business applications and leading AI models (Anthropic Claude, OpenAI, Google Gemini, and open-source models). We handle rate limiting, token optimization, streaming responses, structured schema validation, and secure authentication, ensuring seamless AI adoption without disrupting existing infrastructure.
We believe your digital investments should produce compounding returns. By blending user-centric design with technical rigor, we eliminate friction and build durable digital advantages.
What Sets Our Approach Apart:
- Business-First Focus: We prioritize metrics that move the revenue needle over vanity numbers.
- Senior Execution: Experienced practitioners lead strategy, design, and deployment directly.
- Transparent Delivery: Real-time sprints, clear milestones, and zero proprietary lock-in.
Sub-150ms Middleware Overhead
Ultra-lean Go and Python microservices ensure zero perceptible latency penalty during API brokering.
Model-Agnostic Flexibility
Swap underlying LLM providers (e.g., from OpenAI to Claude 3.5 Sonnet or self-hosted Llama) via unified API abstractions without modifying client code.
High-Concurrency Fault Tolerance
Built-in queue management, exponential backoff retries, and multi-region failovers guarantee 99.99% service availability.
Strict Enterprise Security
End-to-end mTLS encryption, OAuth2/OIDC token authentication, and real-time PII scrubbing ensure zero compliance exposure.
Everything Needed to Scale
Modular, full-lifecycle solutions tailored to your operational model and growth milestones.
Unified Model Gateway Architecture
A single internal API gateway that normalizes requests, manages provider fallbacks, and routes prompts to the fastest, most cost-effective model.
Custom REST & GraphQL AI API Engineering
Developing performant, documented API endpoints (OpenAPI 3.0 specs) tailored to your frontend applications and mobile clients.
Real-Time Streaming SSE / WebSocket Protocols
Implementing Server-Sent Events (SSE) and WebSockets for silky-smooth token streaming and interactive AI experiences.
Vector Database & Embedding Middleware
Scalable ingestion APIs that vectorize, chunk, and index transactional data into Pinecone, Qdrant, or pgvector in real time.
Enterprise Webhook & Event-Driven Pipelines
Asynchronous background processing of intensive AI tasks (video generation, batch document indexing, transcription) via Kafka, RabbitMQ, and AWS SQS.
Token Cost Attribution & Rate Limiting
Granular metering per department, user, or client tenant to monitor inference costs and enforce fair-use API quotas.
See How We Deliver Value

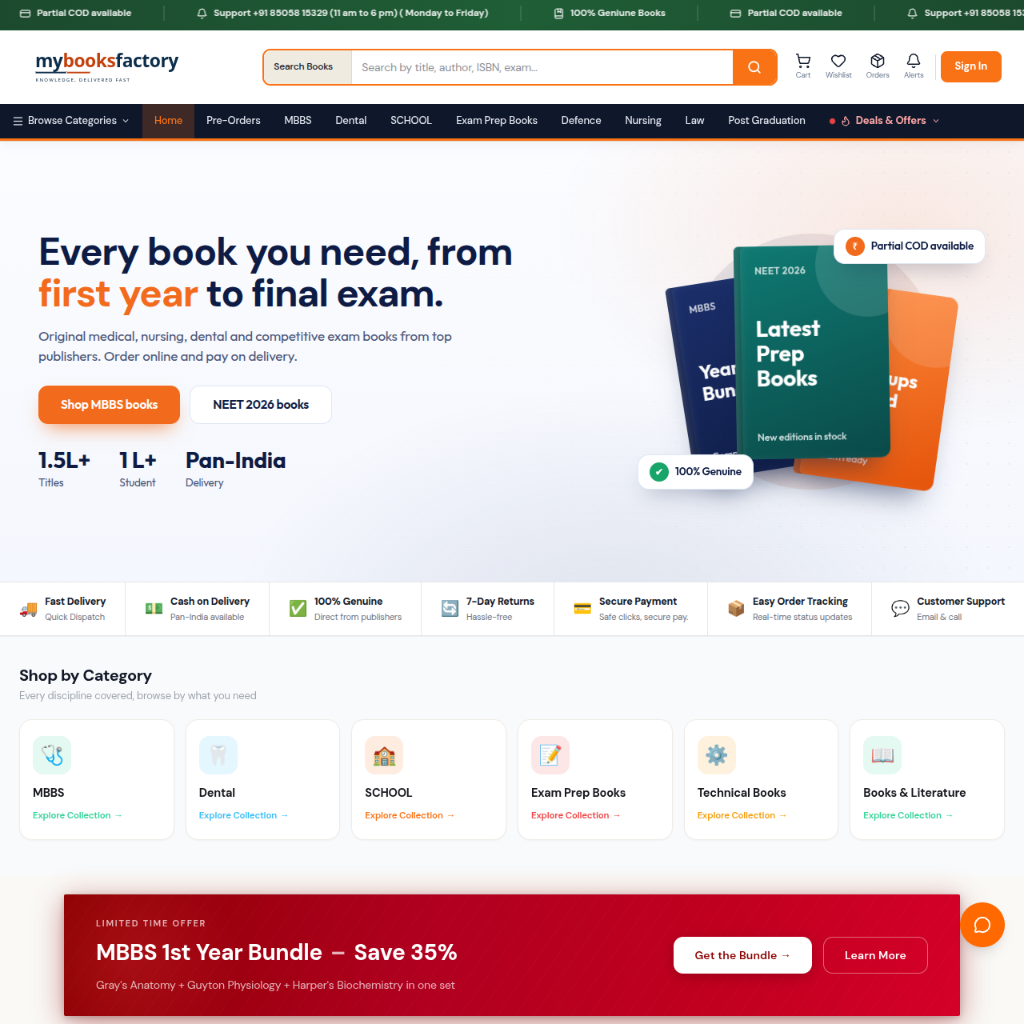
MyBooksFactory — Mybooksfactory.com
MyBooksFactory specializes in medical (MBBS, BDS), engineering, and competitive examination textbooks. We re-engineered their eCommerce platform to handle 40,000+ SKUs with sub-second catalog search and streamlined checkout, boosting sales during peak academic enrollment seasons.
Read Case Study →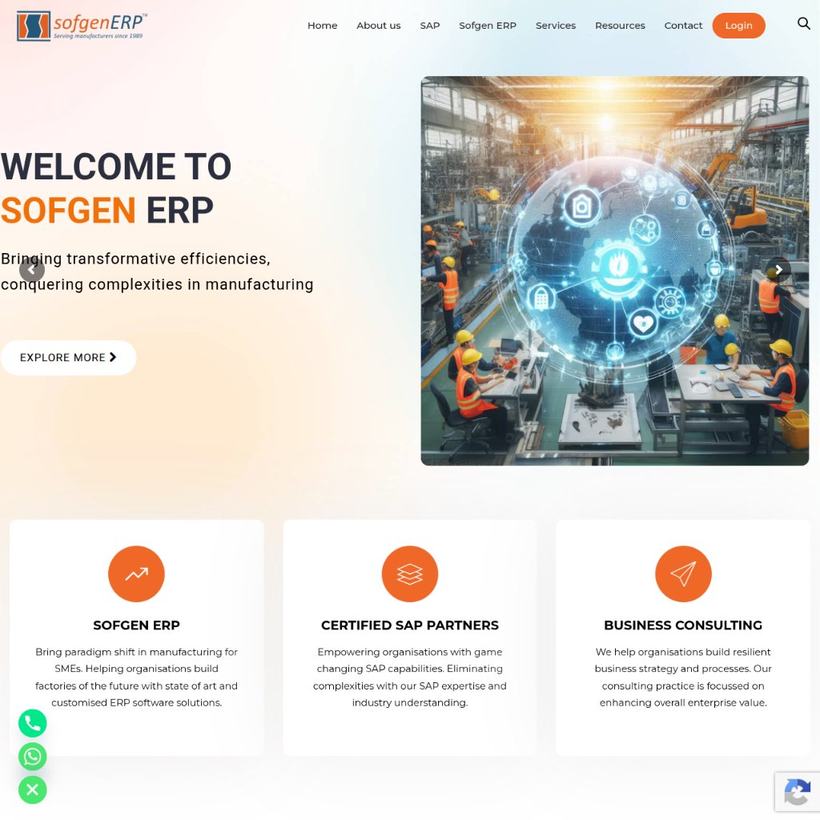
Sofgen ERP — Sofgen.org
Serving high-volume manufacturers since 1989, Sofgen required a cutting-edge digital enterprise flagship to showcase their custom ERP capabilities, certified SAP partnership, and industry 4.0 automation systems. We delivered a performance-optimized Next.js web application with sub-second page loads, structured B2B lead generation funnels, and enterprise solution discovery.
Read Case Study →Frequently Asked Questions
Why do enterprises need custom AI middleware instead of calling model APIs directly?
Direct API calls introduce severe vulnerabilities: lack of fallback when a provider suffers an outage, uncontrolled token costs, absence of PII masking, missing caching layers, and vendor lock-in. Custom middleware provides vendor-agnostic routing, caching, security guardrails, and deterministic formatting.*
Can Accelerance integrate AI into legacy applications with no modern documentation?
Yes. We routinely reverse-engineer legacy database schemas and build secure REST/GraphQL wrapper APIs that allow decades-old enterprise systems to communicate with modern AI models.*
How does dynamic model routing reduce operational costs?
Our intelligent routing gateway inspects incoming query complexity. Simple classification tasks are routed to lightweight, inexpensive models (e.g., GPT-4o-mini or Haiku), while complex reasoning queries are routed to frontier models (Claude 3.5 Sonnet or GPT-4o), slashing overall inference costs by 40–60%.*
What protocols are used for secure enterprise authentication?
We implement industry-standard OAuth 2.0 with JWT verification, mutual TLS (mTLS) for server-to-server communication, and secret management integrated with AWS Secrets Manager or HashiCorp Vault.*
Let’s discuss your project goals.
Connect with our solution architects for a complimentary review of your current systems, roadmap, and growth targets.